APPLIED AI ENGINEER — NEW YORK

Timo Srinarmwong

I make frontier models measurably better — fine-tuning, evaluation frameworks, and agent pipelines for Meta, Snorkel AI, and three frontier research labs.

~84%
human-rated quality gain, Meta Thai LLM
6
eval domains across frontier-lab programs
50+
verified agent-training task solutions
15K
downloads of GOLDI, my solo-shipped iOS app

META  ·  SNORKEL AI  ·  MERCOR  ·  3 FRONTIER RESEARCH LABS

CASE STUDIES

Selected work

01 · META

Teaching Meta's production LLM to speak Thai

Meta's production LLM underperformed in Thai — a low-resource language where generic multilingual data falls short. I paired native-speaker judgment with rubric-driven eval loops and targeted curation: 2,000+ quality-scored examples feeding every fine-tune round.

"Curation beats volume when the evaluator speaks the language."

AI ENGINEER (CONTRACT) · OCT 2024 – JUN 2025 · PYTHON, PYTORCH, FINE-TUNING & EVAL PIPELINES

RESULTS
Human-rated output quality ~+84%
Curated training examples 2,000+
Outcome shipped production gains
02 · MERCOR

Stress-testing models for three frontier labs

Three frontier research labs needed to know exactly where their models fail — before users did. I built cross-domain evaluation frameworks and adversarial edge-case suites across coding, chemistry, cybersecurity, data analysis, reasoning, and applied AI, feeding RLHF and SFT alignment pipelines.

"A model is only as good as the hardest question you ask it."

AI ENGINEER (CONTRACT) · JUN 2025 – JUN 2026 · PYTHON, EVAL DESIGN, RLHF/SFT PIPELINES

RESULTS
Model accuracy across cycles +72%
Scope 3 labs · 5 projects · 6 domains
Hallucination on production outputs measurably reduced
03 · SNORKEL AI

Building the gyms where coding agents train

Flaky environments poison training data. I designed multi-step coding-agent tasks that force genuine end-to-end reasoning, then treated the environments themselves as production software — debugged, hardened, verified with full test suites.

"Agent quality starts with environment quality."

AI ENGINEER (CONTRACT) · JAN 2026 – MAY 2026 · PYTHON, AGENT TASK DESIGN, TEST SUITES

RESULTS
Flaky / failed agent runs ~−30%
Verified solutions w/ test suites 50+
Task environments hardened 15+

CAPABILITIES

How I work

01

MODEL QUALITY & EVALS

Rubrics, eval frameworks, adversarial test suites — turning "make it better" into something measurable.

02

FINE-TUNING & DATA

SFT/RLHF data pipelines, targeted curation, LoRA — quality-scored datasets that move human ratings.

03

AGENTS & TOOLING

Multi-step task design, tool-use evaluation, reproducible environments.

04

SHIPPING

Python, PyTorch, SQL, Swift; Hugging Face, Fireworks.AI, Supabase, Firebase — end-to-end ownership.

timo@nyc — eval_loop.py LIVE
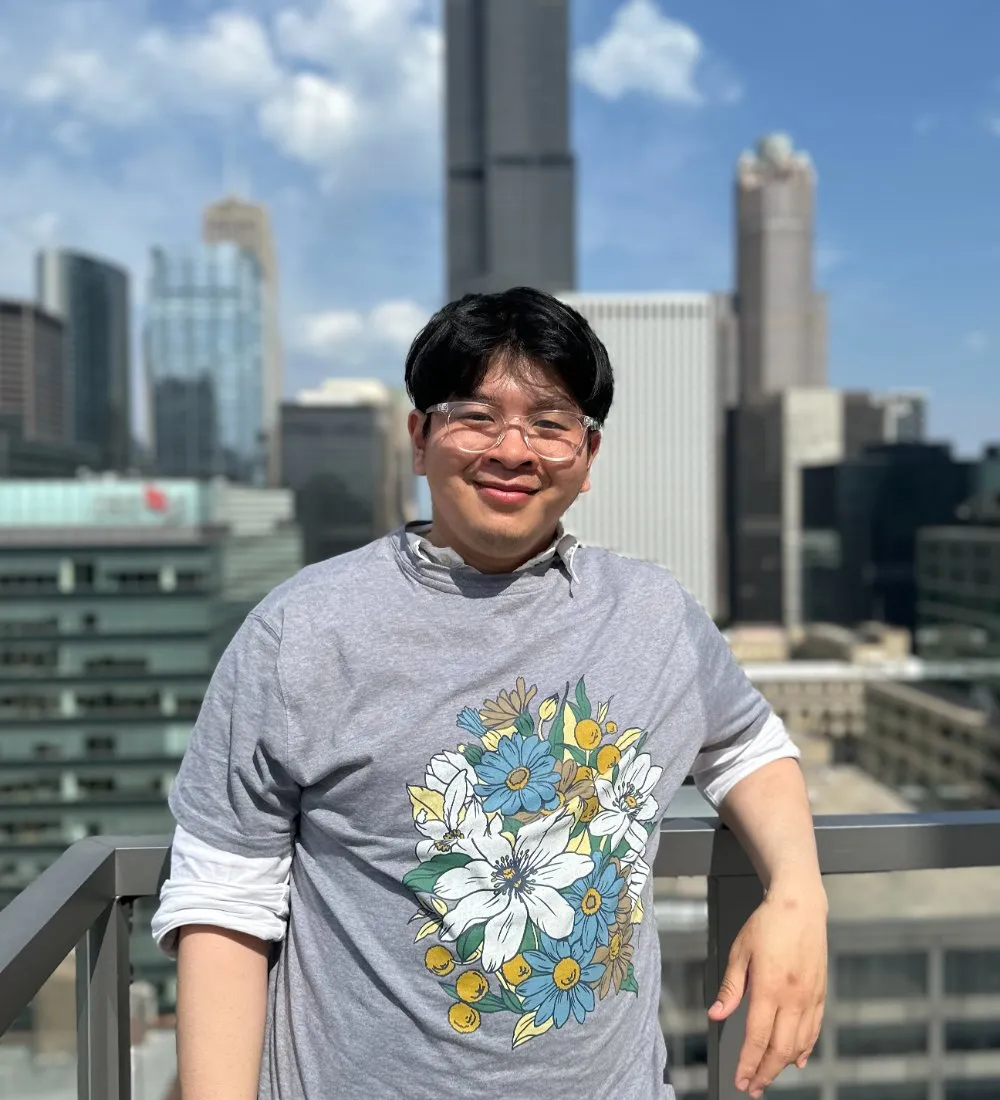
Timo Srinarmwong on a rooftop terrace with a city skyline behind him

ABOUT — NEW YORK, NY

Language nerd turned model whisperer

I started in communications, got obsessed with what makes language work, and ended up with a CS master's from Illinois Tech — teaching machines to use it better. Along the way I shipped a solo consumer iOS app to ~15K downloads with zero paid acquisition, and made the call to sunset it when the retention data said so. I like ambiguous problems, honest metrics, and shipping.

GOLDI bill-splitting iOS app · solo design/build/ship · SwiftUI + Firebase · ~15K downloads, zero paid acquisition

Certifications

OpenAI Applied AI OPENAI 2026
Google Data Analytics Specialization GOOGLE @ COURSERA 2021
Deep Learning Specialization DEEPLEARNING.AI @ COURSERA 2021

CONTACT

Let's make your
model better.

I'm in New York and open to Applied AI Engineer roles. Tell me what you're building.

© 2026 TIMO SRINARMWONG · NEW YORK, NY